
Metadata at meemoo
A file that is not or not properly described is difficult to find. The descriptive data – or metadata – associated with a file is very important if you want to make archival content accessible for reuse. Metadata is also crucial for our internal processes and service provision to partners. Furthermore, we want to improve the searchability of the audiovisual content in our archive system, which we do through metadata enrichment and exchangeability.
The metadata currently in our archive system is not sufficiently uniform, and we are working hard to tackle this challenge both today and in the future. Because metadata is intertwined in almost all layers of our operations, it is important to approach this complex issue in a comprehensive way. We distinguish four different aspects within our approach, although there is also some overlap and not all decisions are set in stone.
An example of our work: in our digital intake process, alongside the digital files that enter our archive system, we also receive their associated descriptive data. This is not a simple task! Read what is involved here.

1. Metadata management
Metadata management includes all the processes and infrastructure investments that we make ourselves, so that we can better meet our own and content partners’ needs. This is essential because the amount of data flowing into our archive system is increasing all the time: more content partners are joining us with new (types of) collections, and projects involving artificial intelligence, among other things, are generating new types of metadata. All of this has an impact on what our metadata infrastructure should look like, and what it needs to be able to do.
That’s why we have created a plan for the coming years. In this so-called metadata roadmap, we aim to transform the collection of current and future metadata into a sustainable and accessible collective memory. We are making metadata storage, integration of metadata with user applications and metadata presentation more sustainable, standardised and robust in 5 horizons.
Learn more about the work we are doing:
The first milestone in the metadata roadmap was the development of a knowledge graph, in collaboration with Triply. This application unifies knowledge by making metadata, thesauri, controlled lists and domain models accessible in a uniform way. The metadata that we share on thearchives.be, will eventually come from this graph.
In consultation with our content partners, we are developing a metadata model (link in Dutch), which will allow us to make collections searchable across content partners in a uniform way. We are further refining this model as part of the roadmap.
2. Supporting our content partners and the broad sector
Our content partners, and the cultural heritage sector as a whole, have many questions about metadata management. We’re supporting them in this through training (such as with the open cultural data bootcamp), promoting various good practices, and providing our own and external tools (such as Entry Books). To make all our content partners’ collections searchable in a uniform way, we are developing a metadata model in consultation with them. They can find these models as well as SIP specifications at developer.meemoo.be (link in Dutch).
In the future, we will be happy to continue supporting our partners with reports on the completeness of their data, and with thesauri – because if you can’t link your data to a thesaurus with a single defined data field, the metadata will remain polluted. We’re also planning to delve deeper into metadata quality reporting.
Here are some examples of how we’re supporting our content partners and the sector:
As part of the metadata roadmap, we provide standardised models for our content partners. We manage and document these models so that they are available and usable for everyone.
How to make cultural data findable, accessible and (re)usable? That's the topic of the open cultural data bootcamp. In various rights workshops, we provide cultural organisations with tools to help them to be more aware of metadata involving rights.
Our what specifications? A SIP, or Submission Information Package, packages the media files and metadata from our content partners in a standardised way. This meemoo SIP follows international standards and takes into account our content partners’ input. This allows us to indicate how all information should be packaged for all objects to be delivered consistently and in accordance with our metadata models.
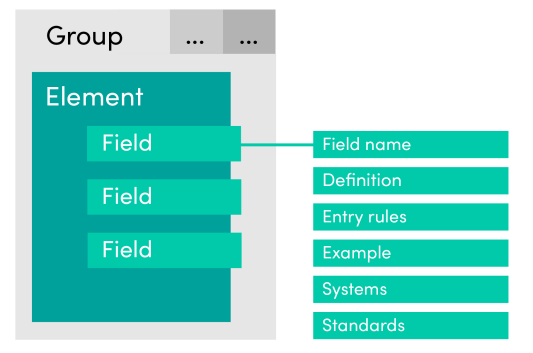
Registrars can use the Objects Entry Book to describe heritage objects in a uniform way so that information about collections is discoverable and usable. The description standards in the Publications Entry Book allow you to document a publication’s key properties.
3. Metadata enrichment
The more qualitative metadata there is, the easier it is to find a file when it is made accessible, for example on thearchives.be or our partners’ platforms. That’s why we’re running several projects to supplement or improve the metadata for files in our archive system. We approach this in two ways: on the one hand, we use the existing metadata (from the content partner themselves or from digitisation projects), and on the other we’re exploring semi-automatic metadata creation. This includes artificial intelligence (AI) techniques such as machine learning and computer vision.
We’re investigating whether we can make connections with linked (open) data and exploring techniques such as speech, entity and facial recognition to enrich descriptive metadata. We’re also paying a lot of attention to creating legal metadata, so you know what you can do with your files and under what conditions.
Specific metadata enrichment projects:
In a project we ran together with the former Flemish Art Collection (now part of meemoo), we connected the VKC ecosystem with the meemoo ecosystem, which allows images and metadata to be exchanged automatically.
In our DO IT! project, we’re using the Public Domain Tool to help ten organisations identify collection items that are in the public domain.
On our educational platform, The Archive for Education, teachers can enhance their lessons with high-quality audiovisual material from our partners. To help them easily find the right image or sound clip, our editorial team carefully provides each item with descriptions and learning object metadata (educational level, grade, subject and theme).
We make use of artificial intelligence for metadata enrichment in the FAME project (facial recognition), the GIVE metadata project (speech, entity and facial recognition), Shared AI (continuation for partners in media) and the Hermes project (for a simplified implementation of new AI applications).
The thousands of newspapers on thearchives.be are searchable thanks to optical character recognition (OCR). This allows you to search the articles themselves for a certain key word.
Some meemoo colleagues wrote a blog about how we’re dealing with the ethical and legal issues that come to the fore with artificial intelligence (and facial recognition in particular).
How we use AI to enrich metadata:
Don't see a video? Please check your cookie settings so we can show this content to you too.
Edit your cookie preferences hereCan’t see the video? Please check that your cookie settings allow us to show you this content. You can change your cookie settings at the bottom of this page. Click on ‘Change your consent’ and select ‘Preferences’.
4. Exchangeability
To store and make information usable in a uniform way, its associated data needs to be structured consistently. By structuring and making datasets available as linked (open) data and linking them to external authorities where possible, we’re making metadata exchangeable. We’re aligning with standards such as the Flemish government’s OSLO standard as well as international standards for this.
Projects to make metadata exchangeable:
A few years ago, research into a common thesaurus between meemoo and the Netherlands Institute for Sound & Vision showed that linking existing thesauri enables a uniform way of searching through different collections.
With the Open Standards for Linking Organisations (OSLO Cultural Heritage), the Flemish government is aiming to adopt a uniform method for exchanging metadata. As product owners, we're fully on board: we organise the OSLO Cultural Heritage working group and promote the use of the standard in the cultural heritage sector, for instance, through the Objects Entry Book or pilot projects.
Every two years, we organise a IIIF Friday to inform and encourage the sector to use IIIF (a standard for image exchange).
We’ve created thesauri for education in collaboration with i-Learn (link in Dutch), so that the same search terms and filters can be used on both The Archive for Education and the i-Learn platform. Find out more about educational structure (link in Dutch) and subjects (link in Dutch).